About Thomas McDonald

This author has not yet filled in any details.
So far Thomas McDonald has created 14 blog entries.

PHP2Shell: What the October 2026 PHP Vulnerabilities Mean for Your Business

Threat Intelligence | Updated October 29, 2026

The October 2026 PHP security crisis raised an immediate question for business leaders: which critical services depend on software their organization may never have inventoried?

On October 21, PHP released emergency security updates addressing two critical vulnerabilities, CVE-2026-109618 and CVE-2026-109619, collectively known as PHP2Shell. Under certain conditions, these flaws allow an attacker to execute code on a vulnerable server without authenticating.

The international response to the PHP security vulnerabilities included urgent patching and precautionary website shutdowns. Those shutdowns should not be interpreted as evidence that every affected organization suffered a breach.

For businesses, the priority is to establish exposure, verify remediation, and determine whether further investigation is warranted. A functioning website provides no assurance that the underlying software is secure.

What Happened—and Why It Matters

PHP processes requests behind many websites and business applications. Its role is often invisible to the people using those services, even when it supports customer transactions, account access, or operational workflows.

The PHP Foundation’s technical explanation of the vulnerabilities identifies two problems in the language’s memory management and error handling:

  • CVE-2026-109618: An out-of-memory condition can leave internal request data partially initialized, creating a path to memory corruption.
  • CVE-2026-109619: Internal state can retain references to memory from an earlier request, creating a use-after-free condition.

Researchers demonstrated remote code execution. Apache deployments using mod_php were particularly concerning because one demonstrated attack could occur before application code executed. PHP-FPM also had confirmed application-level attack paths.

That distinction matters operationally. Exposure depends on the runtime, configuration, and application behavior. Organizations should avoid assuming that a different hosting configuration removes the need to assess and remediate affected systems.

Business Exposure Extends Beyond the Public Website

A PHP assessment should include customer portals, online stores, content management systems, custom applications, and services operated by outside vendors. Older deployments, secondary domains, and staging environments also deserve attention when they remain accessible.

Consider a company whose marketing agency manages its website while another provider hosts a customer portal. Each provider may control a separate PHP installation. Confirmation that the marketing site was patched says nothing about the portal.

The financial consequences depend on what those systems support. An interrupted checkout affects revenue. An unavailable portal can increase support demand. A compromised application may expose information or credentials accessible to its operating account.

The business costs of unplanned downtime therefore belong in the response decision. Leadership needs to understand which functions could stop, what alternatives exist, and how long the organization can operate without them.

Five Priorities for the Response

1. Establish a Complete Inventory and Assign Ownership

Ask the technical team to identify every PHP deployment supporting the business and record:

  • The application and business process it supports.
  • Its hosting location and exposure to external traffic.
  • The deployed PHP package and maintenance provider.
  • The person responsible for approving and implementing changes.
  • The evidence needed to confirm remediation.

Include systems maintained by agencies, software vendors, and hosting companies. An inventory is only actionable when each entry has an accountable owner.

Where information remains unavailable, record that uncertainty explicitly. “Awaiting provider confirmation” should remain an open item with a deadline.

2. Verify the Fix in the Running Environment

The October 21 releases addressing the original vulnerabilities were PHP 8.5.12, 8.4.27, 8.3.36, and 8.2.35. Some vendors supply backported fixes, so a version string alone may not establish whether a vendor-maintained package is vulnerable.

Subsequent guidance also matters. An October 23 advisory addressed session upload progress under particular configurations, and updated Windows packages followed on October 26 for a separate Brotli dependency vulnerability. Technical teams should use the current PHP security advisories and package guidance when validating remediation.

Require evidence from the deployed environment: the installed package, applicable vendor advisory, deployment time, and confirmation that services are running the corrected build. A completed change ticket should be supported by technical verification.

After the change, test the business functions that matter—authentication, transactions, uploads, integrations, and scheduled processing. Document unresolved failures and their owners.

3. Obtain Specific Answers From Hosting and Software Providers

A general assurance that a provider “takes security seriously” does not resolve an exposure question.

Request written confirmation of which services were assessed, whether they were affected, what remediation was applied, and when it became effective. Ask whether the provider identified suspicious activity and what evidence supports its assessment.

Effective vendor risk management and ongoing oversight should make those responsibilities clear before an emergency. Contracts and operating procedures should establish security contacts, escalation routes, and expectations for communicating material vulnerabilities.

For services the business cannot inspect directly, provider evidence becomes especially important. Track unanswered questions alongside internally managed remediation work.

4. Assess Whether Investigation Is Required

Remediation and compromise assessment answer different questions. Installing a correction does not establish what happened before it was applied.

The security team should assess the exposure period, available telemetry, and signs of abnormal activity. Depending on the environment, review may include unexpected file changes, unusual processes, unexplained outbound connections, and unauthorized account activity. These are general investigative leads, not definitive indicators unique to PHP2Shell.

Where suspicious activity is identified, preserve relevant evidence and activate the organization’s response procedures. A clearly defined incident response plan with assigned roles and documentation procedures helps coordinate technical investigation, management decisions, and communications.

An absence of alerts should be interpreted in the context of monitoring coverage. Limited logging can constrain the conclusions an investigation can support.

5. Manage Exceptions as Business Decisions

Some applications cannot be updated immediately without compatibility testing or vendor involvement. Each exception should identify the affected service, business impact, interim controls, accountable decision-maker, and target resolution date.

Technical teams should evaluate temporary measures against the applicable advisory and the deployment’s actual configuration. Leadership should understand what exposure remains and whether continued operation is justified.

Recovery readiness should be part of that assessment. Confirm that restoration procedures are usable and that the business has a practical alternative if a critical service must be isolated.

What Leadership Should Expect in the Status Report

An effective executive update should make the remaining work visible. It should show:

  • Coverage: Systems assessed and systems still awaiting confirmation.
  • Remediation: Verified fixes, unresolved deployments, and completion dates.
  • Investigation: Findings, evidence reviewed, and limitations in visibility.
  • Operational impact: Service interruptions, workarounds, and recovery readiness.
  • Accountability: Named owners for every outstanding action.

Avoid reporting a single “percent patched” figure without explaining its scope. Completing updates on known servers provides limited assurance if third-party applications remain unassessed.

Strengthening Readiness Before the Next Disclosure

PHP2Shell illustrates the importance of knowing where critical software runs and who can act when an urgent vulnerability emerges. The same information supports routine maintenance, vendor oversight, and continuity planning.

Organizations should use the response to improve asset records, clarify emergency change authority, and test provider escalation paths. Any gaps in logging or recovery capability should become assigned improvement work.

For businesses that need additional detection and response capacity, Security+ managed cybersecurity and 24/7 monitoring can support broader visibility across servers, endpoints, and cloud environments. That capability works alongside accountable maintenance and verified remediation.

The immediate management objective is clear: confirm which services were exposed, retain evidence of the corrective action, and resolve the uncertainties that remain.

By Thomas McDonald
2026-10-29T14:47:56-05:00October 29, 2026|

Employee IT Offboarding: A Framework for Access, Devices, and Data Ownership

Employee IT offboarding is an operational handoff involving access, equipment, business information, and accountability. A departure should have a defined completion standard: access restrictions verified, information responsibilities reassigned, devices reconciled, and outstanding exceptions documented.

For business leaders, the central question is whether the organization can demonstrate that each responsibility has been addressed. Closing a support ticket should reflect a completed process, with evidence that the business can continue operating without relying on the departing employee’s accounts or knowledge.

A disciplined framework connects human resources, department managers, and IT through a shared record of decisions, actions, and verification.

Define Ownership Before Work Begins

Every departure should begin with an authorized request identifying the employee, the effective date and time, the responsible manager, and the systems or responsibilities requiring attention. Sensitive departures require carefully controlled communication, with access changes coordinated around the approved timing.

The organization should establish clear responsibilities:

  • Human resources: Authorize the departure notification and confirm its timing.
  • The department manager: Identify business information, ongoing work, and responsibilities that need a successor.
  • IT: Execute approved technical changes and record the results.
  • The designated process owner: Track completion, escalate unresolved items, and approve closure.

Smaller organizations may assign several responsibilities to one person. The requirement is clarity: each action needs an owner, a deadline, and a defined result.

A single departure record should connect those activities. Separate emails and informal requests make it harder to establish whether an instruction was approved, acted upon, or verified.

Build the Offboarding Scope From the Actual Environment

Use the employee’s role and the organization’s technology records to establish what must be reviewed. Include assigned equipment, business applications, administrative responsibilities, shared resources, and external provider accounts.

Consistent documentation of systems, application inventories, and support contacts provides a starting point for this work. Validate those records with the employee’s manager and relevant application owners rather than assuming the inventory is complete.

The review should answer practical questions:

  • Which accounts and permissions are associated with the employee?
  • Which applications require a separate administrator or vendor to make changes?
  • Does the employee own shared workspaces, recurring reports, or business workflows?
  • Which customers, suppliers, or internal teams depend on those responsibilities?
  • What remains uncertain, and who will resolve it?

For example, a departing department manager might be responsible for a shared project workspace and a recurring operational report. The handoff should identify a successor and verify that both remain usable after the approved account changes. This is a planning scenario, not evidence of a specific client incident.

Separate Access Restrictions From Information Decisions

Access removal and information preservation require coordinated decisions. The manager should identify the business material that needs a successor, while IT determines the supported method for implementing the approved changes.

For organizations using Microsoft 365, Microsoft 365 employee offboarding procedures cover blocking access, preserving mailbox content, managing mobile-device access, transferring access to OneDrive and Outlook information, and removing licenses and accounts.

Those procedures also identify options such as email forwarding and shared mailbox conversion. The appropriate choice should follow the organization’s business requirements and the applicable product guidance. Account deletion, license changes, and preservation decisions should be coordinated rather than treated as interchangeable steps.

Apply the same decision discipline to other business applications. Ask the responsible administrator to confirm how access will be restricted, how business information will remain available, and what must happen before the account is removed.

Record the verification result for each system. If an application requires a vendor to complete the work, retain that confirmation in the departure record.

Assign Responsibility for Business Information

The department manager should identify who will take responsibility for active work, shared files, customer communications, and other business information. That assignment should specify what the successor needs to access and why.

Preservation decisions should follow established business data retention policies and documented exceptions. The relevant policy should define retention periods, responsibility for enforcement, and the handling of exceptions. A departure should not become an informal decision to retain everything indefinitely or delete information without review.

Where retention instructions are unclear, refer the decision to the designated policy owner before authorizing deletion. Record the resulting instruction so IT can execute a defined requirement.

The handoff should include a practical check by the receiving manager or employee. Confirm that required material is accessible and that responsibility for ongoing work has been accepted. Transferring access is one action; confirming that the business can use the information is the completion test.

Reconcile Equipment and Its Next Approved Use

Compare returned equipment with the employee’s assigned asset record. Document which devices were received, their condition, and any items still outstanding. For remote employees, establish a return method, responsible contact, and expected receipt date.

The departure workflow should connect directly to IT asset tracking, reassignment, and secure retirement. Once equipment is recovered, update its assigned owner and status. Determine whether it will be prepared for another employee, held for an approved purpose, repaired, or retired.

Technical teams should follow the organization’s approved data-handling and device-preparation procedures before reassignment or disposal. Physical possession of a device should not be treated as proof that it is ready for another user.

If equipment remains outstanding, keep the item visible with a named owner and next action. Record any associated access or data concerns for the responsible team to assess.

Require Evidence Before Closing the Departure

A useful completion record should allow another authorized person to understand what was done without reconstructing the process from memory.

At minimum, the record should contain:

  • Authorization: Who approved the departure request and its effective timing.
  • Access verification: The systems reviewed, actions completed, and confirmation of the resulting status.
  • Information handoff: The approved recipient, preservation instructions, and confirmation that required material is usable.
  • Equipment reconciliation: Returned assets, outstanding items, and approved next steps.
  • Exceptions: Unresolved work, accountable owners, deadlines, and any approved interim arrangements.

The process owner should distinguish completed actions from pending requests. “Sent to the vendor” and “confirmed complete by the vendor” represent different states and should remain separate in reporting.

Exceptions should have a review date. An unresolved application account or missing device should remain tracked until the responsible person documents its resolution or an authorized decision about how it will be handled.

Measure the Quality of the Handoff

Leadership can assess the process through a small set of operational measures: access changes completed within the approved window, outstanding equipment returns, unresolved exceptions, and business handoffs accepted by their new owners.

Use those measures to identify where coordination needs improvement. Repeated uncertainty about application ownership should prompt an inventory review. Repeated delays in receiving departure notices should prompt a review of the HR-to-IT handoff.

The purpose is to make incomplete work visible and assign corrective action. A departure process becomes more dependable when its recurring gaps lead to specific changes in documentation, ownership, and execution.

Make Employee Departures a Managed Operational Process

Employee IT offboarding should have the same discipline as other business-critical changes: authorized timing, defined responsibilities, documented actions, and verification before closure.

Cost+ provides managed IT support for end-user management, email, and business systems through Support+, with dedicated support teams and a personal account manager. Organizations evaluating help with employee transitions should establish the required responsibilities, system coverage, and completion evidence as part of that discussion.

A well-defined departure process gives leadership a clear record of who acted, what was verified, and what still requires attention. That is the standard to build into every employee transition.

By Thomas McDonald

2026-10-29T17:03:47-05:00September 17, 2026|

Recurring IT Problems: How Businesses Can Address the Underlying Causes

Recurring IT problems deserve a different management response from isolated support requests. When the same disruption returns, leadership needs visibility into what remains unresolved, who owns the investigation, and how the organization will evaluate the corrective action.

Restoring service is an immediate operational priority. Establishing why the interruption occurred requires additional work. A closed ticket can document a successful recovery while leaving questions about the underlying cause unanswered.

Businesses should manage those questions explicitly. A practical framework connects related incidents, evaluates their business impact, tests explanations against evidence, and carries approved corrective work through to verification.

Separate Service Restoration From Problem Resolution

A workaround can be appropriate when employees need to resume work. Restarting an application, restoring a previous configuration, or providing an alternate workflow may reduce the immediate interruption. The team should document what the action accomplished and what remains unknown.

Consider a hypothetical application that becomes unavailable during a recurring business process. Restarting it restores access, but the interruption returns during a later cycle. The restart demonstrates that service can be recovered. It does not establish why the application failed.

The next investigation should examine the conditions surrounding those failures rather than treating each occurrence as an unrelated request. That distinction gives leadership a clearer view of recovery activity and unresolved corrective work.

Use separate records or clearly differentiated statuses for service restoration, investigation, and corrective action. Employees can receive confirmation that service is available while the underlying issue remains assigned for further review.

Identify Patterns Without Assuming a Common Cause

Begin with a review of related support records. Group incidents by affected service, reported symptoms, timing, location, and available technical evidence.

Similar descriptions are a reason to investigate a possible relationship. They are not sufficient proof that the incidents share one cause. Two employees reporting a slow application may be experiencing different problems.

A useful review should establish:

  • What happened: The observed behavior and affected business function.
  • When it happened: The timing, duration, and relevant operating conditions.
  • Who was affected: The users, departments, locations, or customers involved.
  • What restored service: The action taken and its observed result.
  • What remains uncertain: Missing evidence, untested explanations, and unresolved dependencies.

Consistent IT documentation for systems and dependencies gives investigators context for interpreting those records. Application inventories, network diagrams, configuration notes, and support contacts help establish where further investigation should begin.

When documentation is incomplete, assign the missing information as part of the investigation. Record assumptions clearly so they do not become accepted explanations without verification.

Prioritize the Business Consequence

Repeated incidents should be evaluated through their effect on operations. Ticket volume is one input; it should be considered alongside the importance of the affected process, the duration of interruptions, and the effort required to work around them.

A recurring issue affecting a critical transaction may warrant attention even if few people report it. A frequently reported inconvenience may justify a different response when its impact is limited and an acceptable workaround exists.

Ask the business owner to identify delayed work, interrupted customer activity, missed processing windows, or additional manual effort. Where costs are estimated, document the assumptions and distinguish estimates from recorded expenses.

The resulting priority should explain why the investigation matters and what decision it is intended to support. That provides a basis for allocating technical time, obtaining vendor assistance, or approving corrective work.

Investigate Contributing Conditions and Record the Evidence

An investigation should distinguish observations from explanations. “The application failed during processing” is an observation. A proposed explanation requires supporting evidence.

Structured incident reviews and corrective action planning provide a framework for documenting impact, examining contributing causes, and identifying measures that reduce the likelihood or impact of recurrence.

Keep the review focused on systems, operating conditions, and decisions. The objective is to understand what allowed the disruption to occur and where improvements are justified. Multiple contributing factors may require attention.

Assign an investigation owner and define the next question to resolve. The record should identify evidence collected, explanations considered, and findings that support or contradict each explanation. If the available information does not establish a cause, report that limitation directly.

Turn Findings Into Controlled Corrective Work

A finding becomes operationally useful when it supports a specific action. Describe the proposed change, the condition it addresses, the expected result, and the evidence needed to evaluate that result.

Each corrective action should have:

  • A named owner responsible for delivery.
  • A priority tied to the business impact.
  • Any required vendor input or approval.
  • A planned implementation date.
  • A test and verification approach.
  • A documented response if the change does not produce the expected result.

Established IT change management and controlled implementation support the approval, testing, communication, and rollback planning needed to introduce a fix responsibly.

Some findings may support a configuration adjustment. Others may require a vendor correction, equipment replacement, or a change to an operating procedure. The recommendation should follow the evidence and account for the consequences of making the change.

If corrective work is deferred, record the reason, the remaining impact, and the next review date. That keeps the decision visible to the people accountable for the affected service.

Verify the Outcome Under Relevant Conditions

Completing an implementation task should trigger verification. Define the acceptance criteria before making the change so the team knows what a successful result will look like.

Verification should reflect the conditions under which the issue appeared. An interruption associated with a periodic business process should be evaluated when that process runs again. A quiet period without comparable activity provides limited evidence about whether the correction worked.

Compare the observed behavior with the original symptoms, review relevant technical records, and obtain feedback from the affected business owner. Document the verification period and any limitations.

If the issue returns, use the new evidence to reassess the explanation and corrective action. Preserve the investigation history so the next review can build on what has already been tested.

Keep Persistent Workarounds Visible

Leadership may decide that a workaround is acceptable while a longer-term correction is evaluated. That decision should identify its owner, operating requirements, and review date.

Repeated manual intervention deserves attention when it becomes part of normal operations. Evaluate how much effort it requires, whether it depends on particular individuals, and what happens when the workaround is unavailable.

This is where recurring issues can connect to the business cost of technical debt. Deferred corrective work should be visible in planning, with its continuing burden considered alongside the cost and benefit of remediation.

Not every issue warrants immediate replacement or redesign. The objective is an informed decision supported by evidence, with clear responsibility for reviewing it as business needs change.

Make Accountability Part of the Support Process

A useful management review should show the recurring problems under investigation, their business impact, assigned corrective actions, overdue decisions, and verified outcomes.

Keep measures distinct. Service restoration time describes recovery performance. Completion of corrective work describes delivery. Recurrence under comparable conditions helps assess whether the intervention addressed the original problem.

Cost+ provides dedicated IT support for business systems through Support+, including desktop, server, cloud, email, database, network, and connectivity support. Dedicated support teams, a personal account manager, and follow-up are part of the published offering.

When discussing recurring issues with a support provider, establish who owns the investigation, how findings will be communicated, and what evidence is required before corrective work is considered complete. Those expectations give leadership a practical basis for evaluating progress beyond the number of tickets closed.

By Thomas McDonald

2026-10-29T17:53:03-05:00August 15, 2026|

The Business Cost of Technical Debt: A Framework for Mid-Sized Organizations

What Technical Debt Actually Is

The term originated in software engineering, but the concept applies to the entire technology footprint of a business. Every time an organization chooses the faster path over the correct one—patching around a problem instead of fixing it, extending a legacy application instead of replacing it, skipping documentation to hit a deadline—it takes on debt. The shortcut delivers value today. The cost is deferred, not eliminated.

Like financial debt, technical debt has two components. The principal is the total remediation work required to bring systems, integrations, and processes to a modern standard. The interest is the ongoing tax paid on every project in the meantime: slower delivery, higher support costs, fragile integrations, and staff hours consumed managing complexity instead of creating value.

Most organizations pay the interest without ever seeing the invoice. It arrives disguised as a project that ran three months over, a routine change that broke an unrelated system, or a new hire who needed six months to become productive because nothing was documented.

Where Debt Accumulates in Mid-Sized Businesses

Enterprise technical debt conversations tend to focus on sprawling application portfolios. For small and mid-sized organizations, the debt usually concentrates in five areas:

End-of-life platforms. Operating systems and server platforms that have aged past vendor support are debt in its most literal form—the upgrade was deferred, and the balance is now due with interest. Organizations still weighing Windows 10 extended security updates are, in effect, paying interest to postpone a principal payment that grows larger each year.

Aging hardware. Devices and network equipment kept in service past their intended lifecycle create both operational drag and exposure. This category is significant enough that it warrants its own analysis—covered in a previous brief on the hardware security gap—but it is one entry in a larger ledger, and it is best governed through a formal IT asset lifecycle management strategy rather than reactive replacement.

Undocumented customizations. The line-of-business application configured by an employee who left in 2021. The spreadsheet macro the finance team cannot operate without. The integration a former vendor built and no one currently understands. These systems work until the day they do not, and remediation under emergency conditions costs multiples of planned remediation.

Unsanctioned tools. When approved systems fall short, employees route around them. Every unauthorized application quietly adopted by a department adds unmanaged debt—data in unknown locations, licenses no one tracks, security controls no one applied. This is the compounding mechanism behind shadow IT risk, and it grows fastest in organizations where debt in sanctioned systems has already degraded the user experience.

Deferred architecture decisions. The network that was never segmented. The backup strategy designed for a company half the current size. The identity system that predates remote work. None of these are broken in a way a status report would capture. All of them make every future initiative slower and riskier.

Why Executives Should Care Now

Technical debt has always been a drag on operations. Three current dynamics have elevated it to a leadership concern.

Debt blocks AI adoption. Every meaningful AI initiative—from productivity copilots to analytics—depends on clean data, modern identity infrastructure, and integrable systems. Organizations discovering that their data lives in disconnected silos, or that their permission structures cannot safely expose information to AI tools, are discovering their technical debt. The businesses moving fastest on AI are the ones that paid their debt down first.

Debt compounds insurance and compliance exposure. Cyber insurance carriers and regulators increasingly expect supported software, documented environments, and demonstrable controls. Legacy systems that cannot support multi-factor authentication or modern endpoint protection do not merely create risk—they create documented, attributable risk that surfaces in underwriting questionnaires and audit findings.

Debt distorts budgets invisibly. When a fifth of the technology budget services old decisions rather than funding new ones, leadership is not getting the strategy it believes it is paying for. The projects that stall, the initiatives that get scoped down, the timelines that slip—these are frequently debt service payments that were never labeled as such.

A Framework for Getting Ahead of It

1. Build the ledger. Debt cannot be managed until it is visible. Inventory every system, its support status, its documentation state, its dependencies, and its owner. The goal is not perfection; it is a defensible register of what the organization owes itself. An independent IT expense and infrastructure review is often the fastest route to this baseline, because outside reviewers have no incentive to leave inherited decisions unexamined.

2. Price the interest, not just the principal. The remediation cost of a legacy system is only half the equation. Estimate what the system costs annually in support hours, workaround labor, project delays, and risk exposure. Debt with high interest and modest principal—a fragile integration that consumes support time every week—often deserves priority over larger but dormant liabilities.

3. Rank by business consequence. Not all debt is worth paying down. A stable system nearing planned retirement can carry its debt to the grave. A platform underpinning revenue operations cannot. Sequence remediation by what failure would actually cost the business, not by what irritates the technical team most. A quarterly review of the register keeps the ranking honest as business priorities shift.

4. Fund paydown as a standing line item. Organizations that treat debt reduction as a one-time project accumulate new debt the moment the project ends. A fixed allocation—commonly 10 to 15 percent of the technology budget—dedicated to modernization and remediation converts an invisible liability into a managed one. This allocation belongs in annual planning discussions alongside growth initiatives, a topic addressed in the brief on strategic IT planning.

5. Govern new debt at the point of creation. The most cost-effective debt is the debt never taken on. Require that shortcuts be recorded when they are made: what was deferred, why, and when it will be addressed. Deliberate, documented debt is a financing decision. Undocumented debt is simply a future emergency.

The Ownership Question

Technical debt persists in most organizations because no one owns it. Technical teams see it daily but lack the authority to fund remediation. Leadership holds the authority but rarely sees the ledger. The organizations that manage debt well close this gap with a designated owner—someone accountable for maintaining the register, pricing the interest, and presenting the tradeoffs in business terms.

For businesses without a full-time technology executive, this is precisely the function a Virtual CIO or CTO exists to fill: translating accumulated technical liabilities into a prioritized, budgeted plan that leadership can actually govern.

The Bottom Line

Every organization carries technical debt. That is not the problem. The problem is carrying it unknowingly—paying interest through slower projects, rising support costs, blocked initiatives, and compounding risk, without ever seeing a statement. Businesses that inventory their debt, price its true cost, and fund its paydown as a matter of routine convert a silent liability into a managed one. Businesses that do not will keep wondering why every new initiative costs more and moves slower than it should. The debt always gets paid. The only question is whether payment happens on leadership’s terms or on the debt’s.

By Thomas McDonald

2026-08-08T14:46:26-05:00July 17, 2026|

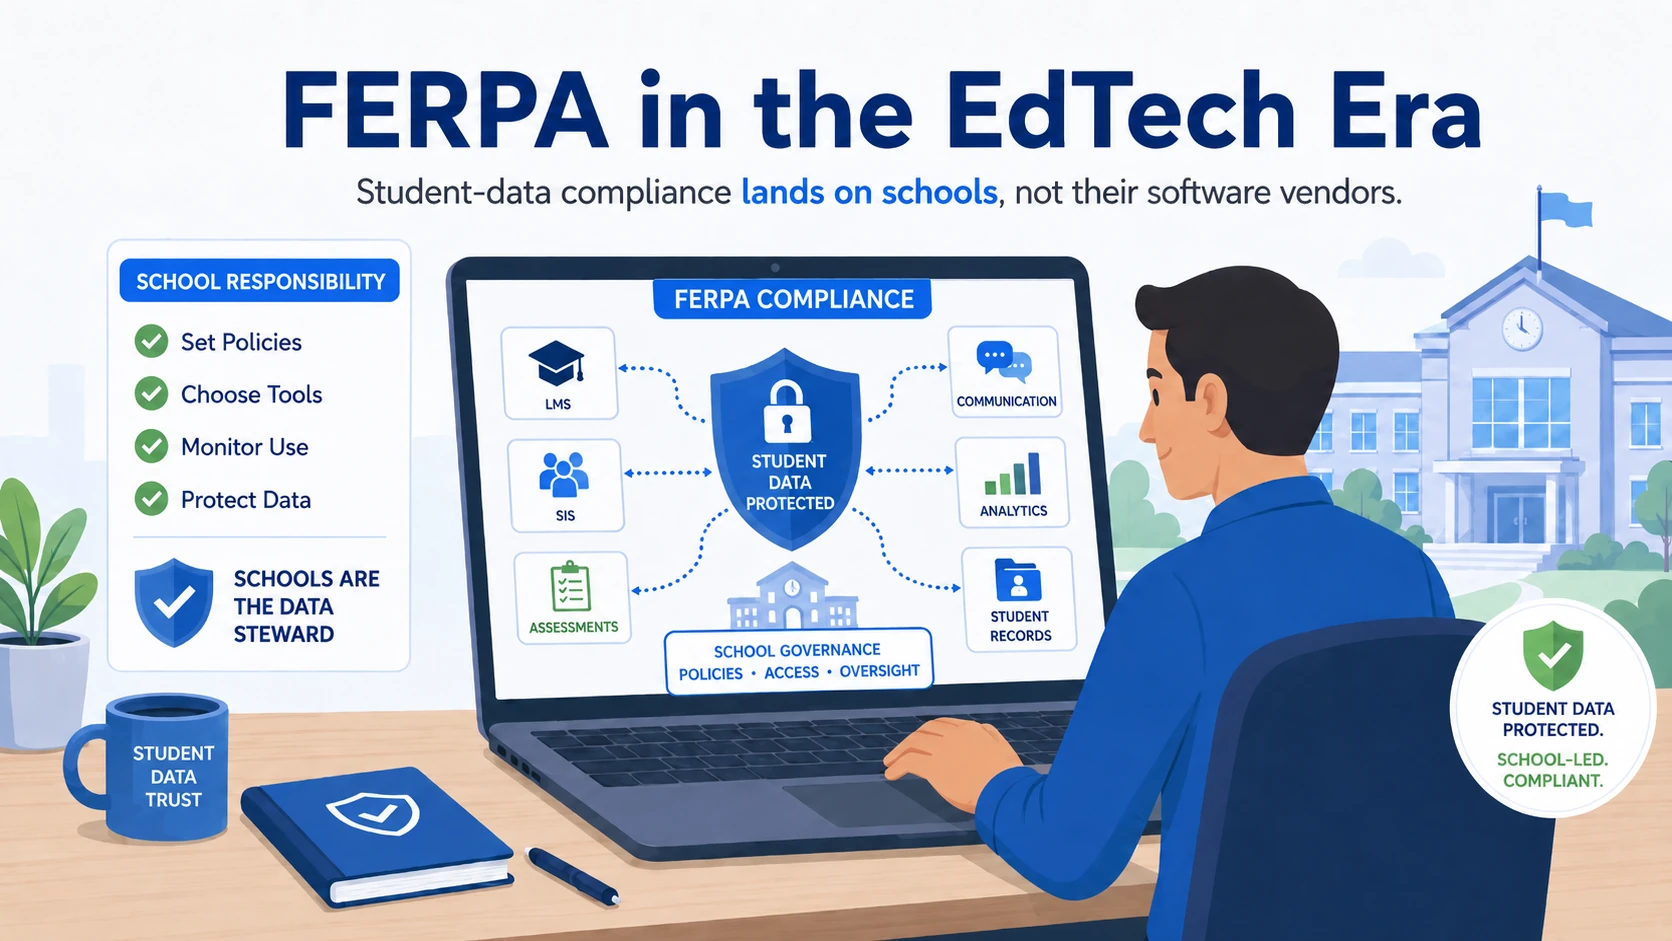
FERPA in the EdTech Era: Why Student-Data Compliance Lands on Schools, Not Their Software Vendors

Few sectors have adopted technology as quickly as education. A single district may run learning management systems, student information systems, assessment platforms, communication apps, tutoring tools, and an expanding roster of AI-assisted products — many of them adopted by individual teachers or departments without a central review. Each of those tools touches student data, and each one represents a point where the institution’s compliance obligations quietly extend beyond its own walls.

That expansion is where many schools and colleges are exposed. The Family Educational Rights and Privacy Act (FERPA) was written in 1974, long before cloud platforms, mobile apps, or machine learning existed. Yet it remains the federal standard governing how student education records are protected and shared — and under its structure, the legal responsibility for that data does not transfer to the vendor holding it. It stays with the school.

What FERPA Actually Governs

FERPA is administered and enforced by the U.S. Department of Education’s Student Privacy Policy Office, which investigates complaints, develops guidance, and provides technical assistance to the education community. The law protects “education records” — broadly defined as records directly related to a student and maintained by an educational agency or institution. That includes far more than grades and transcripts: it can extend to disciplinary records, special-education documentation, identifying information, and the data captured by the digital tools students use every day.

FERPA applies to schools, districts, and postsecondary institutions that receive funding under programs administered by the Department of Education. In practice, that covers virtually all public K-12 systems and most colleges and universities, including private institutions whose students receive federal financial aid. As a general rule, the institution must have written consent before disclosing personally identifiable information from education records — subject to a set of specific exceptions that have become central to how technology is adopted in schools.

The “School Official” Exception — and the Liability It Creates

The exception that matters most in a technology context is the “school official” provision. It allows an institution to share education records, without separate consent, with outside parties that perform a service the school would otherwise handle itself — provided those parties are under the institution’s direct control regarding the use and maintenance of the data, and have a legitimate educational interest.

This is the mechanism that makes modern EdTech possible. When a district adopts a cloud gradebook or a university licenses an analytics platform, the vendor is typically designated a “school official” so that student data can flow to it lawfully. The arrangement is routine, and for the most part it works as intended.

The complication is where accountability sits. Designating a vendor as a school official does not move the compliance obligation to that vendor. If student data is mishandled, exposed, or used outside the agreed purpose, it is the institution — not the software company — that answers for it. FERPA’s ultimate enforcement mechanism is the potential withdrawal of federal funding, and there is no private right of action for families to sue under the statute. But the practical consequences reach well beyond that: federal complaints and investigations, mandated corrective action, reputational damage, breach-notification obligations under state law, and a loss of trust among the families and students the institution serves.

In other words, schools carry the risk for data they no longer physically hold. That asymmetry is the heart of the EdTech compliance problem.

Why the Exposure Is Growing

Three trends have widened this gap considerably in recent years.

Tool sprawl. The number of digital products in use across a typical district has climbed into the hundreds, and by some industry estimates well over a thousand distinct tools are accessed across a district in a given month. Many enter through individual classrooms rather than a procurement process, which means a meaningful share of the data-sharing happening in a school has never been reviewed against FERPA at all.

Vendor breaches as routine events. Concentrating student data in a handful of large platforms creates concentrated risk. The May 2026 incident involving the Canvas learning management system — which took the platform offline during final-exam periods at many institutions — underscored how a single vendor compromise can disrupt operations system-wide and put records belonging to millions of students in question. The Department of Education subsequently sought information from the platform’s parent company regarding its FERPA obligations. For most institutions, the prudent assumption now is that an EdTech vendor breach is an operational risk to plan for, not a remote possibility.

Artificial intelligence. AI-assisted tools that analyze student behavior, generate feedback, or personalize instruction introduce new questions about what data is collected, where it is processed, whether it is used to train models, and how long it is retained. These are precisely the questions FERPA’s “legitimate educational interest” and purpose-limitation principles are meant to address — but only if someone is asking them before a tool is adopted.

A Tightening State-Law Layer

FERPA is the federal baseline, not the ceiling. Over the past decade, states have introduced hundreds of bills addressing student data privacy, and many now impose obligations that go beyond federal requirements — mandatory contract terms with vendors, prohibitions on using student data for advertising, deletion rights, and breach-notification timelines. Long-standing examples include California’s student-data provisions and New York’s Education Law 2-d, and additional comprehensive state privacy laws have continued to take effect into 2026.

For institutions operating across state lines, or serving students who reside in multiple states, this patchwork means a vendor arrangement that satisfies FERPA may still fall short of a specific state’s requirements. Compliance is no longer a single checklist; it is a layered set of obligations that has to be mapped to the jurisdictions an institution actually touches.

What Sound Governance Looks Like

The encouraging reality is that the controls reducing FERPA exposure are the same disciplined IT practices that protect any organization handling sensitive data. They do not require a large team — they require consistency and ownership.

Maintain a real inventory of tools and data flows

An institution cannot govern what it cannot see. A current record of every platform that touches student data — what it collects, where it stores it, and which staff approved it — converts invisible classroom adoptions into a manageable list. This is the single most important step, and the one most often skipped.

Put the agreement in writing before data moves

The “school official” exception depends on the institution retaining direct control over how data is used. That control has to be documented. Agreements should specify the purpose of the data sharing, prohibit secondary uses such as advertising or model training, define breach-notification timelines, and address how data is returned or destroyed when the relationship ends.

Enforce access controls and monitoring

Most student-data incidents trace back to compromised credentials or excessive access rather than exotic attacks. Role-based permissions, multi-factor authentication, and continuous monitoring limit both the likelihood and the blast radius of an exposure. These are core elements of a managed Security+ program and apply directly to the systems where education records live.

Plan for the vendor breach you don’t control

Because so much student data now sits with third parties, an institution’s resilience depends on how quickly it can respond when a vendor is compromised. A tested incident-response process, a current vendor-risk file, and reliable backup and recovery capabilities determine whether a Canvas-style event becomes a contained disruption or a prolonged crisis.

Treat compliance as a continuous program

FERPA obligations are not satisfied by a signed form at the start of a school year. New tools are adopted continuously, vendor practices change, and state requirements evolve. A standing review cycle — supported where appropriate by outside compliance consulting — keeps the institution’s posture aligned with both its tool inventory and the current legal landscape.

Final Thought: The Responsibility Doesn’t Outsource

EdTech has become inseparable from how schools and colleges operate, and the “school official” exception is what allows that ecosystem to function within the law. But the exception governs how data may be shared — not who is accountable for it. That responsibility remains with the institution, regardless of which vendor’s servers the records happen to sit on.

For administrators and IT leaders, the practical takeaway is straightforward. Know which tools touch student data, document the terms under which they hold it, control access to the systems that matter, and prepare for the breach that originates somewhere outside the institution’s own network. In an environment where student records are spread across hundreds of platforms and a single vendor incident can affect millions, that visibility is not a regulatory formality. It is the foundation of protecting the students an institution is entrusted to serve.

By Thomas McDonald

2026-06-07T16:09:31-05:00June 7, 2026|
Go to Top